Machine Learning Engineering
Poisoned at the Source: How Label Errors and Annotator Bias Corrupt Machine Learning Pipelines End to End
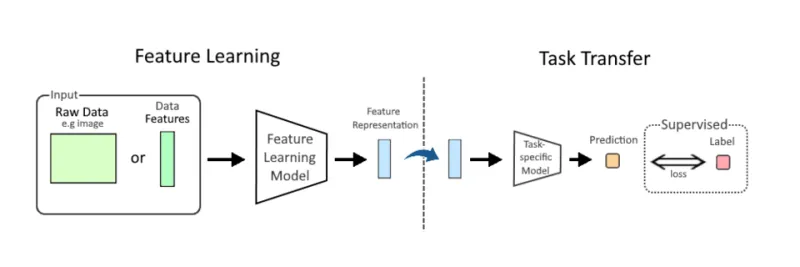
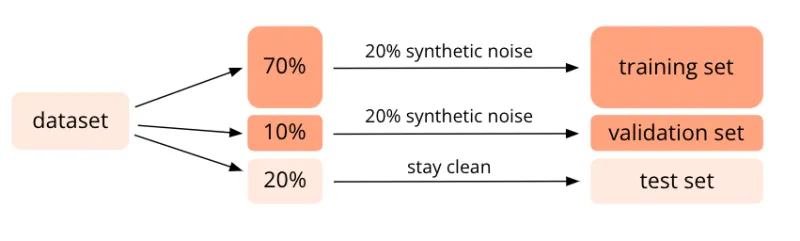
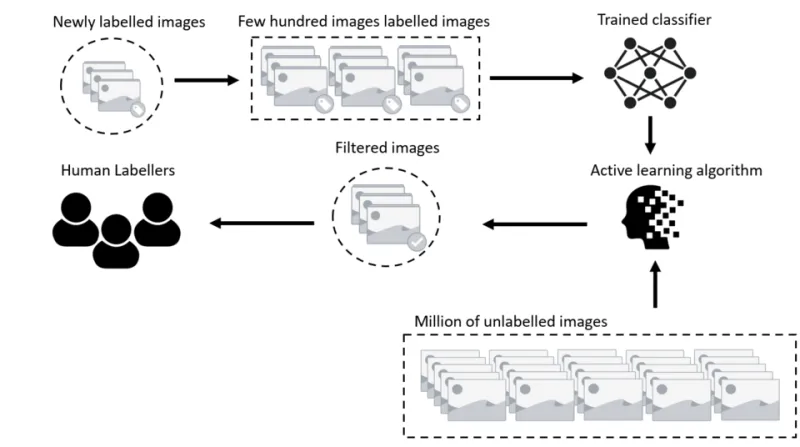
Machine learning systems inherit the biases of every human who touched their training data—often without any record of how or where that contamination entered the pipeline. This technical investigation traces how annotation errors and crowdsourced labeling decisions compound through augmentation, fine-tuning, and deployment, producing models that express confident predictions built on structurally flawed signal.