When the Signal Corrupts Itself: Bit-Level Errors and the Invisible Degradation of AI Inference at Scale
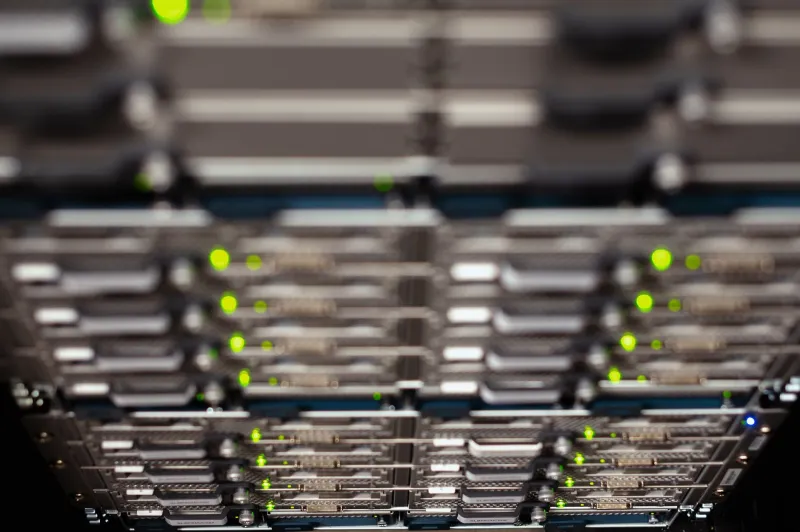
In computing, the assumption of reliable hardware is so deeply embedded in software engineering culture that it rarely surfaces as a design variable. Engineers architect for network failures, model drift, and data pipeline inconsistencies. Rarely do they architect for the possibility that the physical memory storing a model weight has silently flipped a single bit—and that this flip is now propagating through every inference request served to users.
This is not a theoretical concern. It is a documented, measurable phenomenon that has quietly compromised production AI systems across cloud infrastructure, financial modeling platforms, and large-scale recommendation engines. Understanding it requires descending from the abstraction layers that modern software encourages and engaging directly with the physics of computation.
The Physics Beneath the Abstraction
Dynamic random-access memory (DRAM) stores information as electrical charge in capacitor cells. These cells are susceptible to charge leakage, electromagnetic interference, and—most notably—high-energy particle strikes from cosmic radiation. When a neutron or alpha particle collides with a memory cell, it can discharge the capacitor and flip a stored bit from 1 to 0 or vice versa. This event, known as a soft error or single-event upset (SEU), occurs without any physical damage to the hardware and leaves no persistent trace.
At the scale of a single consumer laptop, the probability of a soft error affecting a meaningful computation in any given hour is low enough to be largely inconsequential. At the scale of a hyperscale data center operating tens of thousands of servers, the probability approaches near-certainty on a daily basis. Google's 2009 study of DRAM errors in production infrastructure found error rates significantly higher than manufacturers' specifications suggested, with some DIMM modules exhibiting rates orders of magnitude above the population average.
The problem has not diminished in the intervening years. If anything, the transition to higher-density memory, the proliferation of accelerator hardware (GPUs and TPUs), and the expansion of AI inference workloads have created new surface area for soft errors to matter in ways they previously did not.
Why AI Inference Is Particularly Vulnerable
Not all computations are equally sensitive to bit-level corruption. A flipped bit in a database record containing a customer's zip code is likely to produce an obviously invalid value that downstream validation catches. A flipped bit in a neural network weight is considerably more insidious.
Modern large language models and deep learning inference systems operate on floating-point representations—typically 16-bit (FP16) or 8-bit (INT8) quantized values in production environments optimized for throughput. A single bit flip in a floating-point exponent field can shift a weight value by several orders of magnitude. A flip in the sign bit inverts it entirely. Neither event produces a crash. Neither produces an out-of-range error. The model continues executing, silently producing outputs that have been subtly—or dramatically—distorted.
The cascade effect is what distinguishes AI inference from simpler computational workloads. In a deep neural network, activations from one layer feed forward into the next. A corrupted weight in an early layer does not merely affect one output; it contaminates every downstream calculation that depends on it. Depending on where in the network the corruption occurs and which weights are affected, a single bit flip can manifest as a systematic bias across an entire class of inputs—consistently misclassifying certain image types, consistently skewing sentiment scores in a particular direction, or consistently miscalibrating risk estimates in a financial model.
Documented Cases and Their Costs
Publicly documented incidents of soft-error-induced AI inference degradation are rare, not because the events are rare, but because they are difficult to attribute with certainty and because organizations are understandably reluctant to disclose them. Nevertheless, several cases have entered the technical literature and engineering community discussion.
In cloud provider post-mortems, unexplained variance in inference quality that could not be attributed to model updates or data distribution shifts has, upon investigation, occasionally traced back to memory subsystem anomalies on specific host machines. The challenge is that the symptom—slightly degraded output quality on a subset of requests—is easy to dismiss as statistical noise until the affected hardware is identified and the correlation becomes apparent.
Financial institutions running inference pipelines for risk scoring and fraud detection face a particularly acute version of this problem. A corrupted weight that systematically underestimates fraud probability for a specific transaction pattern does not generate an alert. It generates approvals. The cost accumulates invisibly until a human analyst notices an anomaly in realized loss rates—a lagging indicator that may follow the original corruption event by weeks or months.
One well-circulated case from a US-based quantitative trading firm (discussed at a systems reliability conference without full organizational attribution) involved an inference node that had been serving slightly miscalibrated probability estimates for approximately eleven days before the error was isolated. The firm's post-incident analysis estimated the total cost impact in the low seven figures, attributable to a single memory module that had not been flagged by standard hardware health monitoring.
Detection Strategies and Their Limitations
The engineering response to soft errors has historically centered on error-correcting code (ECC) memory, which encodes data with additional redundancy bits that allow single-bit errors to be detected and corrected transparently. ECC is standard in server-grade hardware and represents the first and most effective line of defense.
However, ECC is not a complete solution in the context of AI inference workloads. Several limitations are worth noting.
First, ECC protects data in memory but does not protect data in transit across memory buses, within GPU VRAM (where ECC coverage varies by product tier), or within the computational logic of accelerator chips themselves. High-performance AI accelerators prioritized for throughput may offer partial or optional ECC coverage, and operators under cost pressure sometimes disable it to recover the associated performance overhead—typically three to five percent.
Second, ECC corrects single-bit errors but can only detect (not correct) double-bit errors. At sufficient memory density and radiation exposure, multi-bit upsets are non-negligible.
Third, and most practically significant, ECC tells an operator that a correction occurred. It does not tell them whether the correction happened before or after the corrupted value was read into an accelerator's computational pipeline and used in a forward pass. In high-throughput inference environments, the sequence of events between a memory read and an ECC correction can be operationally ambiguous.
Beyond ECC, engineering teams have begun implementing application-layer consistency checks—running duplicate inference passes on sampled requests and flagging divergent outputs, maintaining statistical baselines of output distributions and alerting on drift, and periodically re-running stored inference requests against known-good outputs to detect regression. These approaches add latency and computational overhead but provide coverage that hardware-level mechanisms cannot.
The Economics of Error Correction at Scale
The cost-benefit analysis of investing in robust error correction is straightforward in principle and complicated in practice. ECC memory and its associated infrastructure carry a premium. Redundant inference passes double compute costs on sampled traffic. Comprehensive monitoring pipelines require engineering investment and ongoing operational overhead.
Against these costs, operators must weigh the expected value of errors they are preventing—which requires estimating both the frequency of consequential bit flips and the dollar impact of the decisions those flips affect. For a content recommendation system, a subtly miscalibrated model may produce engagement metrics that drift imperceptibly. For a medical imaging inference system or a credit risk engine, the same miscalibration may carry regulatory and financial consequences that dwarf the cost of prevention.
The practical conclusion most serious operators have reached is that the cost calculus changes sharply with deployment scale and with the stakes of the decisions being automated. At scale, soft errors are not a remote possibility—they are a scheduled event. The question is not whether a bit will flip, but whether the infrastructure surrounding it is designed to contain the consequences when it does.
Decoding the Signal in Production
The broader lesson embedded in the soft-error problem is one that aligns closely with how rigorous computing research must approach production AI systems: the signal is always degrading. Physical reality imposes noise floors that no amount of software abstraction eliminates. Engineers who treat hardware as a perfectly reliable substrate are not modeling the system they actually operate.
Detecting and correcting for bit-level corruption in AI inference pipelines is, at its core, an exercise in signal recovery—the same discipline that underlies reliable communication, error-correcting storage, and fault-tolerant distributed systems. The tools exist. The awareness, in many engineering organizations, is still catching up to the scale of the problem.
For organizations deploying AI inference at any meaningful scale, the immediate practical steps are concrete: audit ECC coverage across all inference hardware, establish output distribution baselines and automated drift detection, implement sampled redundancy checks on high-stakes inference paths, and include memory subsystem health in post-incident review checklists when unexplained model behavior is observed.
The cascade begins with a single bit. Whether it ends there depends entirely on what the surrounding system was designed to do when the signal corrupts itself.